
Backup & Restore configuration
General information
OpenCRVS dependencies helm chart has an configuration options for automated backups and restores.
OpenCRVS dependencies helm chart includes a built-in backup and restore features that supports automated backups and restores for internal components (data stores). Backups are uploaded on an external server via an SSH connection.
Supported data stores:
PostgreSQL
MinIO
Backup and restore configuration flow
"Deploy dependencies" GitHub Actions workflow configure backup and restore at deployment time and creates all required secrets.
The following outlines the high-level backup and restore configuration:
Production servers should be configured to run backup jobs only.
Staging servers should be configured to run restore jobs only.
The private SSH key used by the restore job must match the one used on the production server.
The backup encryption key on the production server and the restore decryption key on the staging server must be identical.
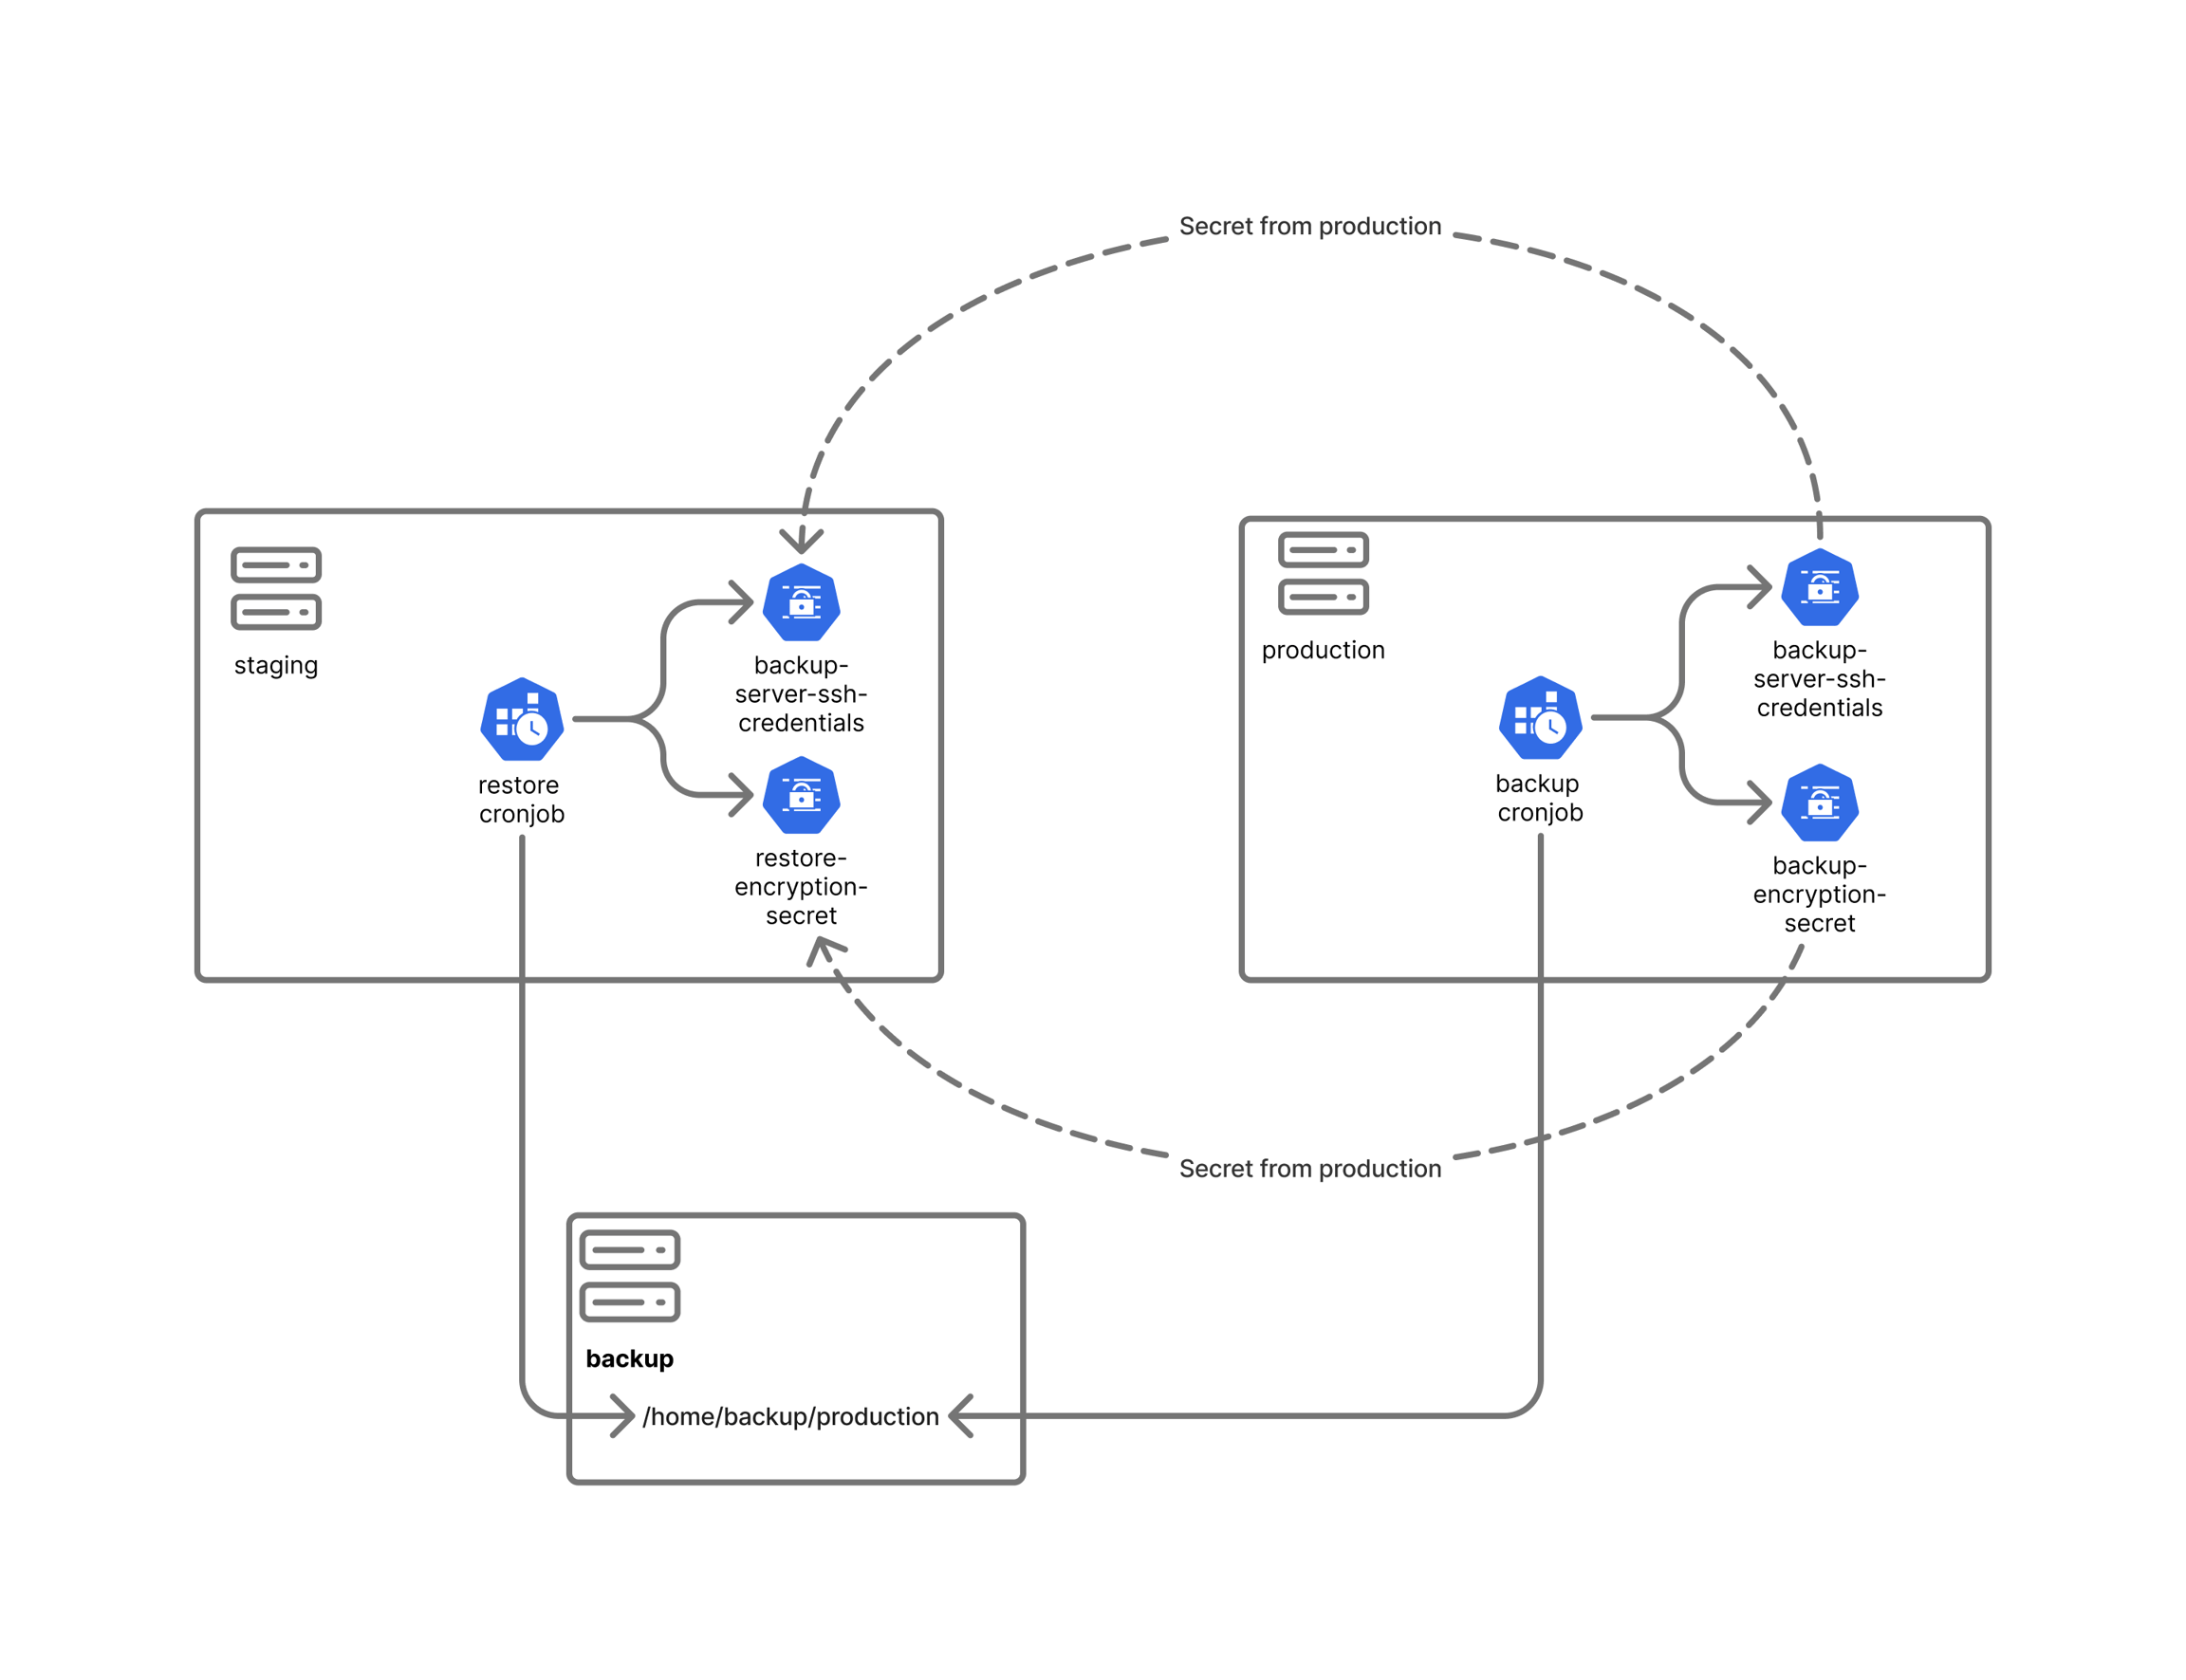
Backup types
Following backup types are supported by data stores:
Postgres:
dump: (Default) Database dump, without instance configuration. Backup is performed bypg_dumputility. Database credentials are preserved. Backup is suitable for average country with small population (up to 1 million of people).differential: Differential backup between last full backup. Backup is performed at instance (cluster) level bypgBackResttool. Database credentials are replaced with credentials from backup server at restore time. By default weekly full and daily differential backups are made.
MinIO:
dump: (Default) Full filesystem copy clone archived and encrypted on daily basics.differential: Full filesystem copy mirrored on remote backup server folder with rsync.
Please check helm chart documentation and values.yaml for more information about available configuration options. Backup schedule and backup types.
Backup and restore configuration
Each datastore has its own backup job, implemented as a Kubernetes CronJob. Backup and restore settings are defined in the backup (restore) section of the chart values file. Each datastore can have its own schedule and remote directory on the backup server.
The backup server hostname is set with backup.host (restore.host) in the chart values, while the SSH user and key are stored in the backup-server-ssh-credentials secret. The yarn environment:init script populates the hostnames from the BACKUP_HOST and RESTORE_HOST GitHub environment variables.
Example:
Refer to the Helm chart documentation and values.yaml for details about the available configuration options. For example, PostgreSQL supports multiple backup types.
Typically, backup jobs are configured only in the production environment, while restore jobs are configured only in the staging environment. However, there are no restrictions on configuring backup or restore on other environments. For example, backup and restore can be configured between development and QA environments for testing purposes.
Backup server configuration is fully automated using Ansible playbooks. To bootstrap a backup server, provide its IP address or hostname to the yarn environment:init script and run the bootstrap process.
Backup server filesystem structure
Full backups are stored as compressed and encrypted archives in the backup server's remote repository. The repository is organized as follows:
Backup directories are structured by date.
Each backup directory contains one encrypted archive for each datastore.
The following example shows the directory structure of the remote backup repository:
Differential backups are stored uncompressed on the backup server and are not organized into date-based directories.
For PostgreSQL, differential backups are managed by pgBackRest. The only configurable option is the destination directory.
In this example the folder /home/backup/production/postgres/ is managed by pgBackRest:
Last updated